Running Quality Score Columns With CTEs
Build data quality signals into your SQL pipelines using CTEs.
A pipeline that reports success has told you nothing about whether the data it moved is correct. It has only told you that no step threw an exception along the way, and the failures that do the most damage downstream are precisely the ones that never throw one. Dashboards, forecasts, and AI models consume pipeline output on the assumption that completion means correctness, but none of these consumers validate the data themselves: they trust the green checkmark and move on. A required field can go NULL across an entire batch, a load can introduce duplicate keys, a value can drift outside the range it was ever supposed to occupy, and in every one of these cases the pipeline finishes and reports success anyway. Corrupted data reaches a dashboard or a model with the same apparent confidence as clean data, and the gap between the two is discovered only after someone has already made a decision based on it. Closing that gap means attaching a computed reliability signal to the data itself, so the signal travels with every row and every consumer downstream can see, at the point of use, how much to trust what they're looking at. That signal is the quality score column, and the rest of this piece is about how to build one with SQL you likely already know how to write.
What a quality score column is
A quality score column is a computed numeric value, appended to a dataset or produced in a final CTE layer, that encodes how closely the data meets a defined set of standards across more than one dimension at once. It is not an alert. An alert fires when a threshold is crossed and then goes silent; a quality score column is a persistent, queryable value sitting in the data itself, available to any downstream process, model, or dashboard that wants to read it. The scoring logic lives inside the transformation and recalculates on every single run, so the score is always as current as the data it describes.
The underlying math is simple enough to carry across any SQL engine. Microsoft Purview's scoring documentation defines it as passed records divided by total records, where total records includes everything that passed, failed, got miscast, or came back empty. That ratio normalizes to a value between 0 and 1, or 0 to 100 if you multiply for readability, and it's the cleanest engine-agnostic definition of what a quality score actually measures. The formula can also flex to match what actually matters for a given dataset: Airbnb's DQ Score weights Accuracy, Reliability, Stewardship, and Usability differently from one another. The arithmetic scales in an orderly way, too. A column-level score is the average across all the rules applied to that column, and an asset-level score is the arithmetic average of the scores of all the rules applied across its columns. That same hierarchy, rule to column to asset, is what a chain of CTEs builds toward when it rolls dimension scores into one composite at the end.
Why CTEs fit multi-dimensional checks
Common table expressions give each quality check its own named stage, and that structure makes the query read like a plain description of the rules it enforces. A CTE, as the advanced SQL canon defines it, creates a named, temporary result set using the WITH keyword, referenced later in the same statement. It exists to make long queries readable, and it can be referenced more than once without being recomputed from scratch each time.
The clearest precedent for this pattern comes from clinical care. A CMS quality measure in clinical care is built as set arithmetic: an Initial Population narrows to a Denominator, the Denominator gets reduced by Denominator Exclusions, a Numerator is identified within what remains, and a Score comes out the other end. Work executing these CQL-authored measures as plain SQL on FHIR data has shown that each of those stages maps cleanly onto its own named CTE, with shared exclusion logic factored out into reusable pieces rather than copied and pasted at every measure, so fixing the logic once fixes it everywhere it's used. The domain there is clinical quality reporting, but the structural lesson transfers directly: a multi-stage population calculation, where each stage depends on the one before it, belongs in a chain of named CTEs.
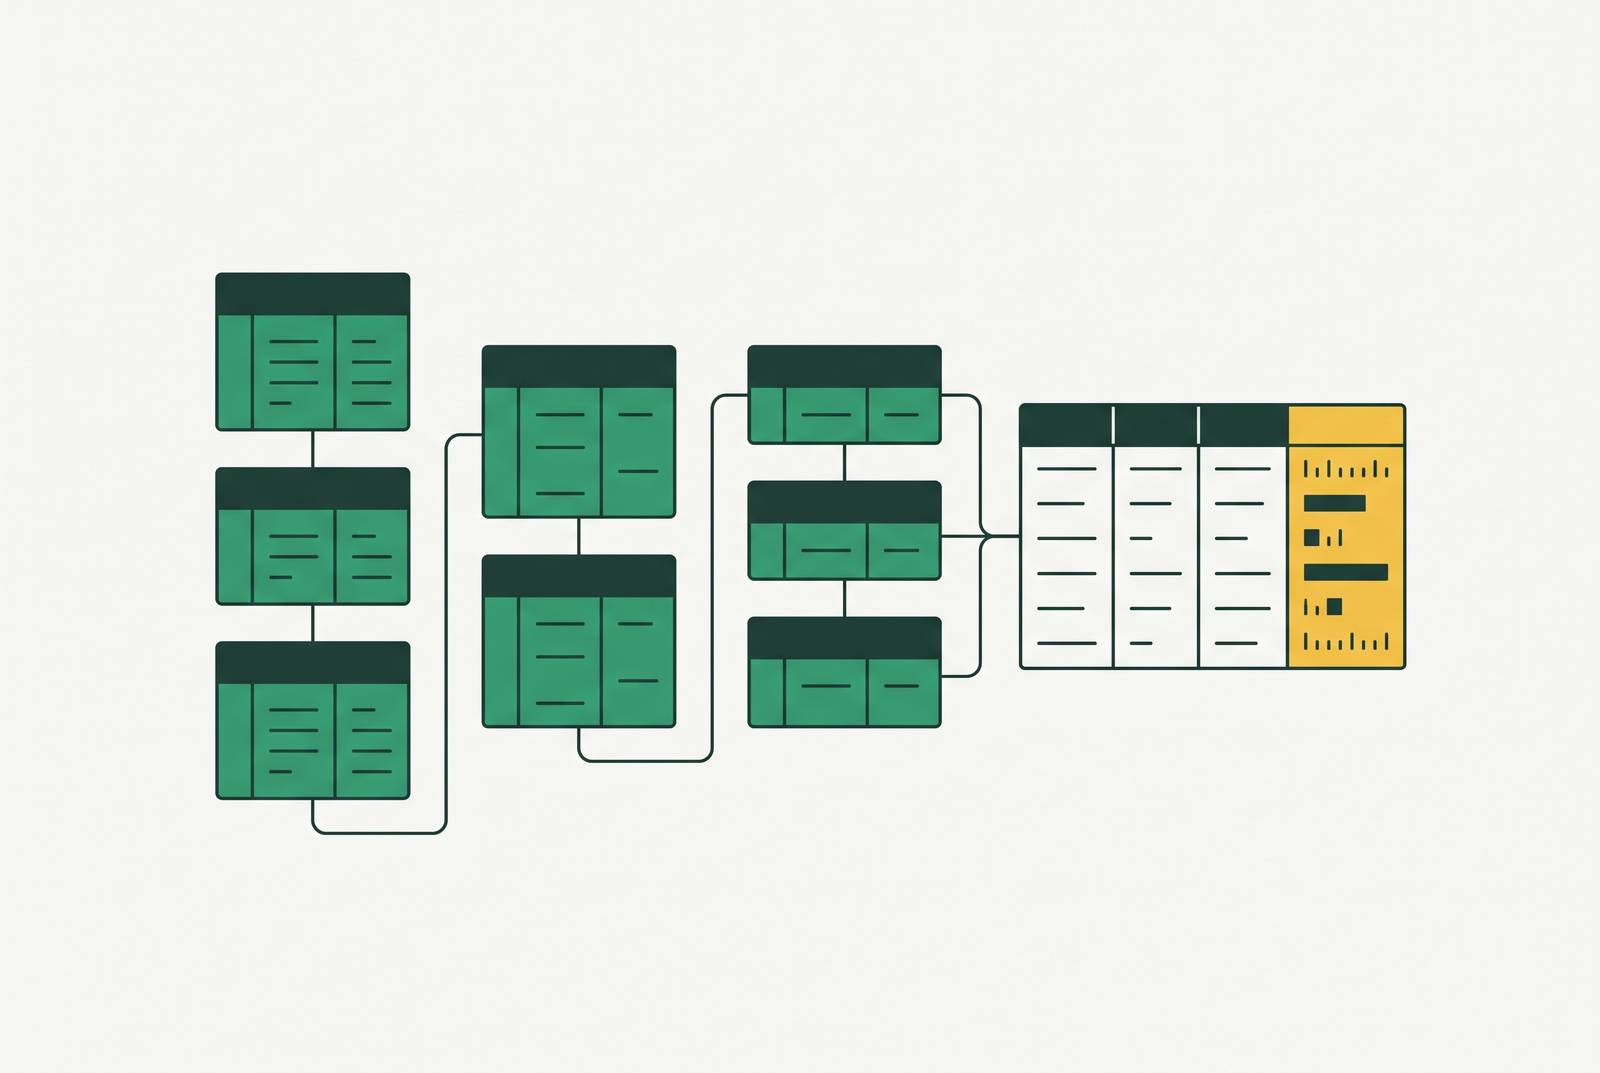
Compare that to the alternative. A deeply nested subquery that computes completeness, then uniqueness, then validity, all folded inside one another, can produce the exact same result as a CTE chain, but nobody can read it. When a rule changes six months later, whoever has to edit it is stuck hunting for which nested layer contains the condition that needs updating. CTEs avoid that entirely, and they offer a development benefit beyond readability: running SELECT * FROM completeness_check in isolation shows exactly which rows failed that one dimension, before the composite score ever gets computed. That inspectability matters when something looks wrong in the final number and the question is which stage is responsible.
Scale is the real constraint: hand-authored CTE checks can't keep pace with hundreds of tables across a large warehouse, and nobody is going to write a bespoke completeness-validity-uniqueness chain for every table a company owns. That's an argument for layering automated anomaly monitors on top of CTE-based gates, not an argument for abandoning the gates themselves. Most practitioners treat rule-based CTEs and automated monitoring as complementary tools solving different problems, the CTEs encoding the specific business rules a team already knows matter, the monitors catching the drift nobody thought to write a rule for. The rest of this piece builds three of those gates by hand: completeness, validity, and uniqueness.
The seven dimensions quality checks draw from, and the three this walkthrough builds
Data quality checks draw from a recognized set of dimensions, grouped under industry standards like ISO 25012 and DAMA into completeness, accuracy and validity, consistency, uniqueness, and timeliness. Within that set, three dimensions are the most universally applicable across systems of record, and they catch the large majority of the silent failures described earlier: completeness, validity, and uniqueness.
Completeness asks whether required fields are actually populated, catching the NULL or blank values that should never have made it into a required column. Validity asks whether the values that are present fall within the domain they're supposed to occupy, covering range checks, pattern checks, lookup or domain checks, and type checks all at once. Uniqueness asks whether a key or combination of fields that should identify exactly one record is in fact doing so, catching the duplicate keys that slip past a database's own uniqueness constraints when those constraints are missing or incomplete.
The remaining dimensions, referential integrity, freshness and timeliness, volume, and distribution, extend the identical CTE pattern. Each one simply becomes its own named stage ahead of the final scoring SELECT, built the same way the three in this walkthrough are built. Not every dimension scores on the same scale, either. Purview's scoring model treats its Freshness rule as strictly pass or fail, a score of either 0 or 100 rather than a ratio, which is a useful reminder that a composite score doesn't require every dimension to be measured the same way. It only requires every dimension to resolve to a number the final SELECT can combine.
CTE 1: measuring completeness across required fields
The first CTE in the chain identifies which records have every required field populated and computes a completeness ratio as passed records divided by total records. Consider a CRM contacts table where the required fields are owner_id, account_id, email, and stage. Any record missing one or more of those four values fails the completeness check, regardless of how complete the rest of that record happens to be.
WITH completeness_check AS (
  SELECT
    contact_id AS record_id,
    CASE
      WHEN owner_id IS NOT NULL
       AND account_id IS NOT NULL
       AND email IS NOT NULL
       AND stage IS NOT NULL
      THEN 1 ELSE 0
    END AS completeness_passed,
    (
      (CASE WHEN owner_id IS NOT NULL THEN 1 ELSE 0 END) +
      (CASE WHEN account_id IS NOT NULL THEN 1 ELSE 0 END) +
      (CASE WHEN email IS NOT NULL THEN 1 ELSE 0 END) +
      (CASE WHEN stage IS NOT NULL THEN 1 ELSE 0 END)
    ) / 4.0 AS completeness_score
  FROM contacts
)
The output has one row per record: record_id, a completeness_passed flag of 1 or 0, and a completeness_score representing the fraction of required fields that are actually populated. That second figure matters because it lets a record with three of four required fields filled in score differently from a record missing all four, even though both would fail a strict pass/fail check. This is the same arithmetic the Purview formula describes at the column level: total passed records divided by the sum of passed, failed, miscast, and empty records, with empty records entering the denominator and dragging the score down.
Completeness checks can go one layer deeper than a simple NULL test. A field populated with the string 'UNKNOWN' or 'N/A' is technically non-null, but it's semantically just as empty as a NULL value would be, and a completeness CTE can extend its CASE logic to treat those sentinel values the same way it treats a true NULL.
CTE 2: checking validity against domain rules and format constraints
The second CTE tests whether the values that did pass completeness actually fall within the domain they're supposed to occupy, and it produces the same per-record flag structure the completeness CTE produced, which is what lets the two stages join cleanly later.
A range check catches values that are numerically present but implausible:
validity_check AS (
  SELECT
    opportunity_id AS record_id,
    CASE
      WHEN standard_cost < 0 OR standard_cost > 10000 THEN 0
      WHEN stage NOT IN ('Prospecting', 'Qualification', 'Proposal', 'Closed Won', 'Closed Lost') THEN 0
      ELSE 1
    END AS validity_passed
  FROM opportunities
)
A negative standard_cost, or one implausibly above 10000, fails the range check regardless of whether the field is populated. The lookup check in the same CASE statement catches a stage value sitting outside the five defined states a CRM pipeline actually recognizes, a classic domain violation that a NULL check alone would never catch since the field isn't empty, just wrong.
A pattern check extends the same logic to email formatting, flagging any value that doesn't match the expected pattern even when the field is non-null. A type-check variant uses TRY_CAST: when TRY_CAST(column AS DATE) returns NULL, the original value couldn't be coerced into the expected type at all, what Purview's documentation calls a miscast, and that miscast enters the denominator of the scoring formula the same way an empty value does. Cross-field validation belongs here too: a close_date earlier than a create_date is a logical inconsistency between two individually well-formed fields, and it fails validity even though neither field alone looks wrong.
The validity CTE's output mirrors the completeness CTE exactly: record_id, validity_passed, validity_score. Because both stages key on the same record identifier, the final scoring SELECT can join them without any ambiguity about which row corresponds to which.
CTE 3: detecting duplicates that uniqueness constraints miss
The third CTE identifies duplicate records on a defined key using ROW_NUMBER(), flagging every occurrence after the first so the resulting score reflects how much of the dataset is genuinely distinct.
uniqueness_check AS (
  SELECT
    contact_id AS record_id,
    ROW_NUMBER() OVER (
      PARTITION BY email, account_id
      ORDER BY created_at DESC
    ) AS row_num,
    CASE
      WHEN ROW_NUMBER() OVER (
        PARTITION BY email, account_id
        ORDER BY created_at DESC
      ) = 1 THEN 1 ELSE 0
    END AS uniqueness_passed
  FROM contacts
  WHERE email IS NOT NULL
)
The composite key here, email plus account_id together rather than either column alone, is the CRM-relevant case: two contact records can carry different contact_id values and still be duplicates of the same person at the same company. Purview's scoring documentation notes that its Unique values rule filters out null values before evaluating uniqueness, and the CTE above follows that same logic by excluding null emails from the partition. A null key isn't a uniqueness failure, it's a completeness failure, and it has already been caught by the first CTE in the chain.
A window function like ROW_NUMBER() produces a result that has to be named and referenced before it can be filtered or joined against anything else, and a CTE gives it exactly that name cleanly, making the strongest case for CTEs over nested subqueries, where the same logic would be buried inside another layer of parentheses. Uber's ETL Manager pattern shows what this signal is for in production: before a pipeline is scheduled, ETL Manager can consume quality results for its input datasets and suspend the pipeline if any of them fail to meet SLA, which is the uniqueness score from a CTE like this one becoming a literal gate condition inside an orchestrator.
All three CTEs now produce the identical output shape, a record_id paired with a passed flag and a score. The final SELECT needs that same consistency to combine them.
The final SELECT: rolling three dimension scores into one composite quality score
The final SELECT joins the three dimension CTEs on the shared record key and computes a composite score that any downstream query, model, or dashboard can read as a single trusted signal.
SELECT
  c.record_id,
  c.completeness_score,
  v.validity_passed AS validity_score,
  u.uniqueness_passed AS uniqueness_score,
  (c.completeness_score + v.validity_passed + u.uniqueness_passed) / 3.0 AS composite_quality_score
FROM completeness_check c
JOIN validity_check v ON c.record_id = v.record_id
JOIN uniqueness_check u ON c.record_id = u.record_id
That unweighted version treats all three dimensions as equally important, an arithmetic mean normalized to a value between 0 and 1. But equal weighting is a default, not a rule, and the Airbnb example cited earlier makes the case for departing from it whenever the use case calls for it. A CRM opportunities table built around forecasting probably needs validity, stage integrity, and close-date plausibility, to carry more weight than uniqueness, since a malformed stage value does more damage to a forecast than an occasional duplicate record. A contacts table feeding an email marketing system runs the opposite risk profile: uniqueness and completeness matter more there, since a duplicate contact or a missing email address breaks the campaign in a way a minor validity issue wouldn't. Assigning those weights is a deliberate design decision made once, at the point the composite formula is written, and it's one more reason the CTE chain belongs inside the transformation itself rather than bolted on as an afterthought: the score that comes out the other end reflects a judgment someone actually made about what reliability means for that specific table.